NEWS // Latest ActivityTOTAL: 010
Gemma 4's "Divergent" Edge Architecture: A Systems Engineer's Breakdown of Memory Wall Breakthrough for Local AI
Zhipu AI Reveals "Scaling Pain": Addressing GLM-5 Coding Agent Anomalies Under High Load with Robust System Engineering
Exploring LLM Architectures: KV Sharing and Compressed Attention
River-LLM Introduces KV-Shared Exit to Achieve Seamless Early Exit and Significant LLM Inference Speedup
DeepSeek's Price Cuts Ignite AI Token Market Reshuffle: Technology Innovation Drives Industry Transformation
SinkRouter: A Novel Training-Free Routing Framework for 2x Faster Long-Context Decoding in LLMs/LMMs
Together AI Open-Sources OSCAR: 2-Bit KV Cache Quantization
Baidu Open-Sources Unlimited OCR: Continuous Document Parsing Beats DeepSeek
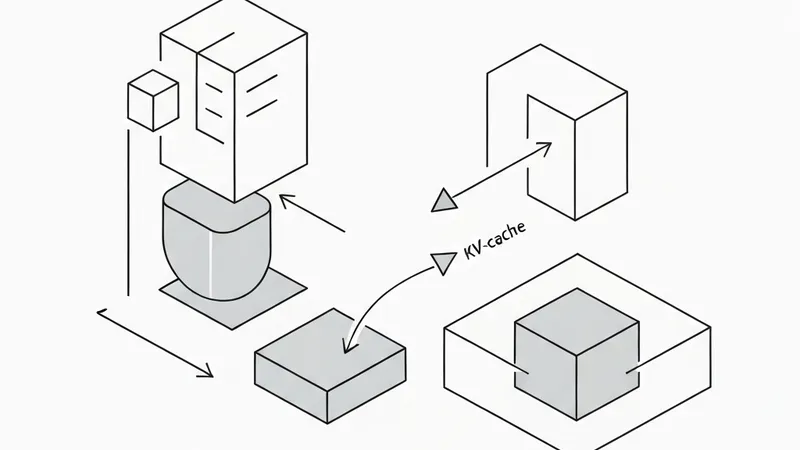
Why Your LLM Doesn't Re-Read the Prompt: The Magic of KV-Cache
SPIN Framework Unifies Sparse Attention with Hierarchical Memory for Scalable Long-Context LLM Serving